AI Model Quality Testing Platform
Don't ship a model withunknown defectsship
Automated quality testing across 18 dimensions — accuracy, safety, hallucination rate, bias and more. Replace gut feel with reproducible data when selecting, accepting and continuously regressing models.
- No sign-up — just enter a key on the right to try it
- Keys deleted right after the run
- Reproducible and traceable results
Major models supported, compared under one standard


Why systematic quality testing matters
A working API call doesn't mean you're ready to ship. The real risks — jailbreaks, fabricated facts, format drift — only surface under systematic evaluation.
18 evaluation dimensions
Accuracy, safety, hallucination rate, bias, robustness, instruction following, reasoning — every dimension that matters, not just a single headline score.
4 intensity levels
A light smoke test, a standard full regression, a deep three-run variance check, or an extreme doubled adversarial stress test — invest to match the situation.
Reproducible, deterministic scoring
Scoring runs on a rule engine, so identical inputs always produce identical scores. Every case is traceable, so the conclusions hold up to review.
Open API access
Embed quality testing in your CI pipeline. Start runs, query results and receive callbacks — all programmatically.
A full evaluation in four steps
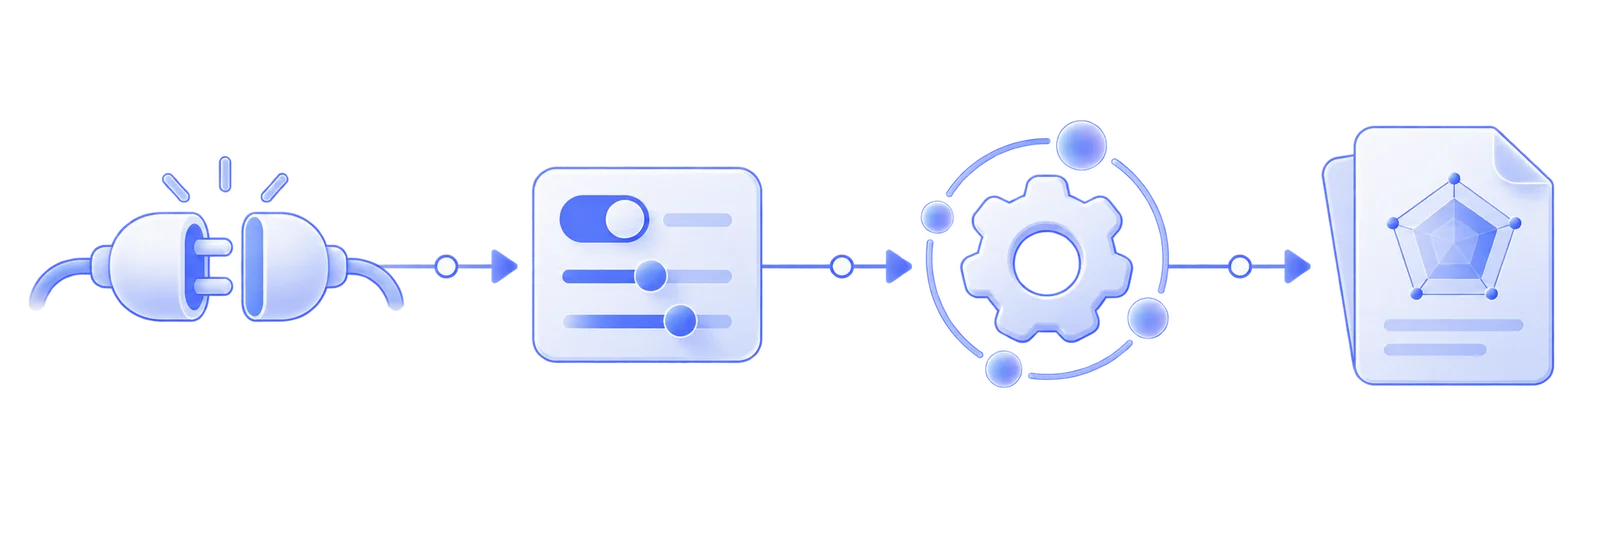
Connect a model
Enter the endpoint and key — any OpenAI-compatible model works. Keys are stored encrypted.
Choose dimensions and intensity
Pick the quality dimensions that matter to you, then set the intensity and tier.
Run the evaluation
Tasks run asynchronously in a queue, calling the model case by case and scoring against rules.
Read the report
Get per-dimension scores, failing-case details and improvement suggestions — exportable and shareable.
Model quality leaderboard
Real data from a single evaluation standard, updated continuously.
Pick what you need, upgrade anytime
From a free trial to enterprise API access — quota and capability grow with your tier.
Free
20 light evaluations a month — enough to see what the platform does.
- 20 evaluations per cycle
- Up to 3 dimensions
- Up to Light intensity
- 1 concurrent tasks
- Reports kept for 7 days
Pro
300 evaluations a month across 8 dimensions at standard intensity, with export and comparison.
Was ¥199.00
- 300 evaluations per cycle
- Up to 8 dimensions
- Up to Standard intensity
- 3 concurrent tasks
- Reports kept for 90 days
- Team collaboration for 3 people
- Side-by-side model comparison
- Report export and sharing
Pro (annual)
Save 60% paying annually, with the full quota credited up front — best for sustained use.
Was ¥2388.00
- 3600 evaluations per cycle
- Up to 8 dimensions
- Up to Standard intensity
- 3 concurrent tasks
- Reports kept for 180 days
- Team collaboration for 3 people
- Side-by-side model comparison
- Report export and sharing
Enterprise
API access and team collaboration, with deep intensity fully unlocked.
Was ¥999.00
- 2000 evaluations per cycle
- Up to 14 dimensions
- Up to Deep intensity
- 10 concurrent tasks
- Reports kept for 365 days
- Team collaboration for 10 people
- Side-by-side model comparison
- Report export and sharing
- Open API, 50000 calls per cycle
Teams making decisions with evaluation data
Deep evaluation brought the hallucination rate down to a shippable level
After adopting an LLM for customer-service Q&A, this team hit a problem: the model was inventing product terms. A deep evaluation across the hallucination-rate and accuracy dimensions pinpointed three high-risk question patterns. After reworking the prompts, the re-test score rose from 62 to 89.
“The report surfaced failing cases we hadn't even thought of — far more useful than testing on instinct.”
Multilingual evaluation backed the decision to launch in Southeast Asia
During selection they used the platform to compare four candidate models side by side on multilingual ability and instruction following. Data replaced opinion, and the decision was made within two weeks.
“The comparison table turned our selection meeting from an argument into a look at the numbers.”
FAQ
Which models can the platform evaluate?
The platform works with any OpenAI-compatible model service, including self-hosted and privately deployed models. Enter the endpoint and API key and you're ready to evaluate.
Which dimensions do you evaluate?
There are 18 dimensions: accuracy, safety, hallucination rate, bias, robustness, instruction following, consistency, relevance, completeness, fluency, concision, reasoning, coding, multilingual ability, privacy compliance, jailbreak resistance, response performance and cost efficiency.
What's the difference between intensity levels?
Intensity sets how many cases are drawn and how often they repeat. Light is a quick check; Standard covers every case once; Deep repeats three times to measure variance; Extreme doubles the cases and repeats five times for formal certification.
How is quota calculated?
Each run deducts quota as tier level × intensity multiplier. The exact cost is shown before you submit, and you can't submit without enough balance.
When does quota reset?
Subscription quota resets each billing cycle. Top-up pack quota stays valid through its term and never resets with the cycle.
Is there API access?
The API is available on Enterprise and above. Create an application in the console to get a key, then start evaluations, query results and receive callbacks over the API.